Frugal and Robust Audio Models
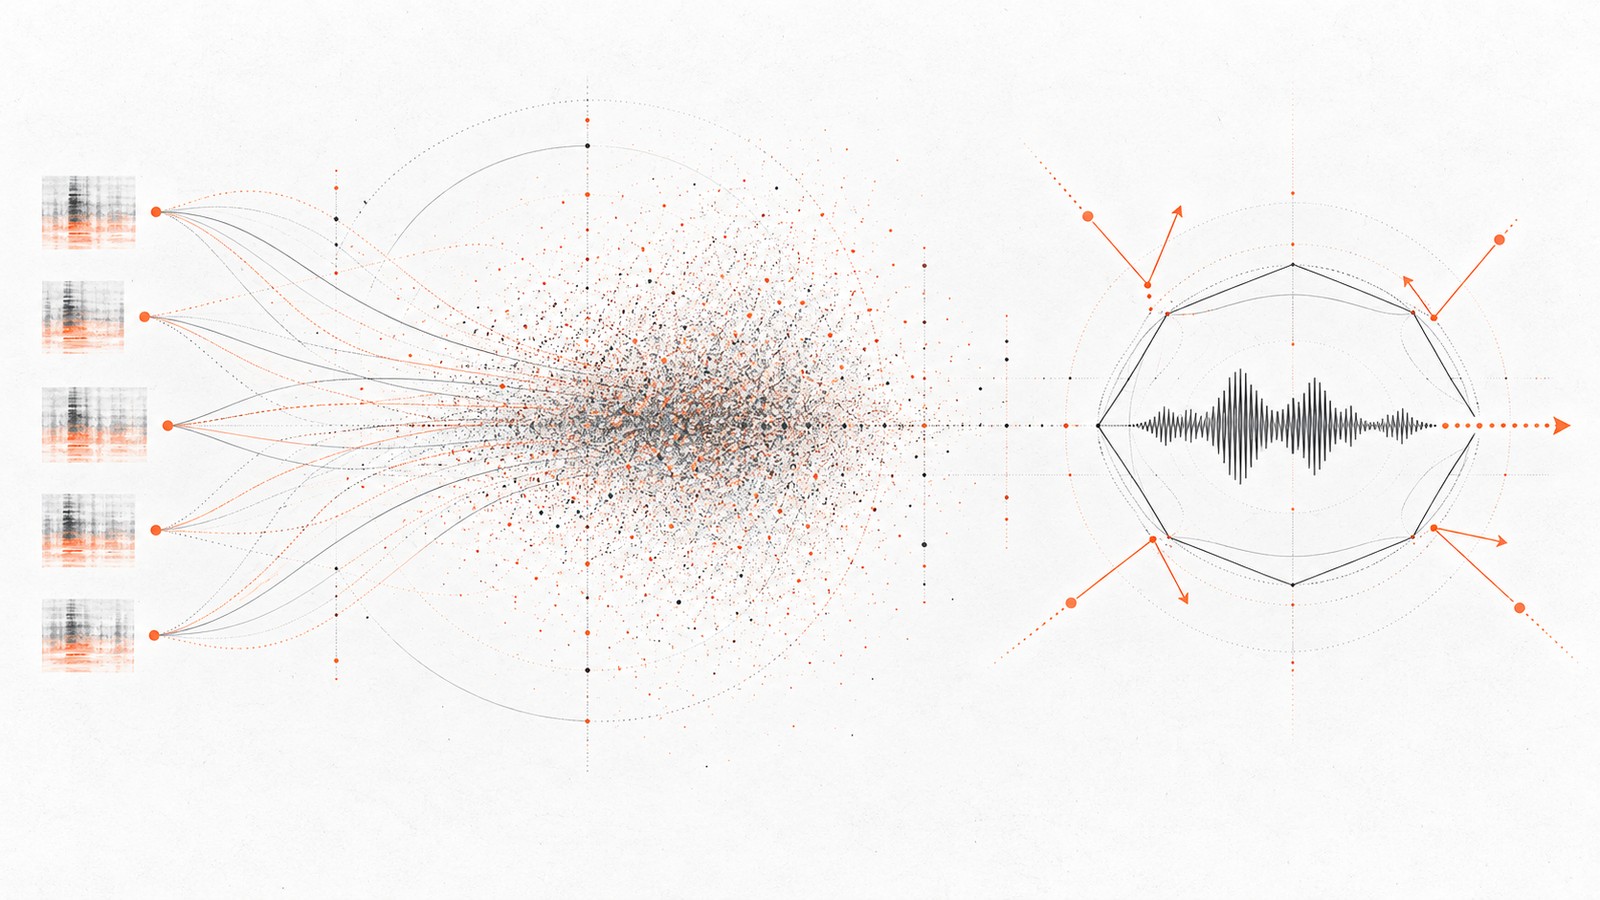
Most audio research assumes abundant labels, generous compute and a cooperative world. Applied settings assume none of the three. The interesting questions start when a class has five examples, the model has to run on a constrained device, and somebody has an incentive to fool it.
Few labels
We work on few-shot audio classification, combining prototypical networks with contrastive learning, and evaluate few-shot architectures across audio benchmark datasets rather than on a single favourable one. Where labels have to be created, we have built an AI-powered framework for streamlined image and audio annotation, because annotation cost, not model capacity, is usually what decides whether a project happens.
An adversary
State-of-the-art transformers for sound event classification are vulnerable to black-box adversarial attacks, and we study how vulnerable, and to what. The code is released as a repository exploring those vulnerabilities, so that a claim of robustness can be tested rather than asserted. This complements our robustness work in speech emotion recognition, where the adversary is not a person but the world.
Where this runs
FaRADAI — Frugal and Robust AI for Defence Advanced Intelligence — is the EU project this line was built around. Our contribution covered semi-automatic data annotation, multimodal fusion for military applications, adversarial robustness in audio and few-shot learning.
Selected publications and resources
- On the Robustness of State-of-the-Art Transformers for Sound Event Classification Against Black Box Adversarial Attacks 2025 EUSIPCO. IEEE doi
- Prototypical Contrastive Learning For Improved Few-Shot Audio IEEE MLSP (2025) doi
- An AI-Powered Framework for Streamlined Image and Audio Annotations Artificial Intelligence for Security and Defence Applications III, Vol. 13679, pp. 495-513, SPIE (2025) doi
- Speech-music discrimination using deep visual feature extractors Expert Systems with Applications 114 (2018): 334-344. doi
Open resources: audio-adversarial-attacks, audio-few-shot-learning, and deepaudio-x, which trains classifiers on self-supervised backbones with minimal code.